
The goal of this writing is to explain which applications are suitable to be ported to OpenCL and run on GPU (or multiple GPUs). It is done by showing the main differences between GPU and CPU, and by listing features and characteristics of problems and algorithms, which can make use of highly parallel architecture of GPU and simply run faster on graphic cards. Additionally, there is a list of issues that can decrease potential speed-up.
It does not try to be complete, but tries to focus on the most essential parts of assessing if code is a good candidate for porting to the GPU.
GPU vs CPU
The biggest difference between a GPU and a CPU is how they process tasks, due to different purposes. A CPU has a few (usually 4 or 8, but up to 32) ”fat” cores optimized for sequential serial processing like running an operating system, Microsoft Word, a web browser etc, while a GPU has a thousands of ”thin” cores designed to be very efficient when running hundreds of thousands of alike tasks simultaneously.
A CPU is very good at multi-tasking, whereas a GPU is very good at repetitive tasks. GPUs offer much more raw computational power compared to CPUs, but they would completely fail to run an operating system. Compare this to 4 motor cycles (CPU) of 1 truck (GPU) delivering goods – when the goods have to be delivered to customers throughout the city the motor cycles win, when all goods have to be delivered to a few supermarkets the truck wins.
Most problems need both processors to deliver the best value of system performance, price, and power. The GPU does the heavy lifting (truck brings goods to distribution centers) and the CPU does the flexible part of the job (motor cycles distributing doing deliveries).
Assessing software for GPU-porting fitness
Software that does not meet the performance requirement (time taken / time available), is always a potential candidate for being ported to a GPU. Continue reading “Selecting Applications Suitable for Porting to the GPU”
 Ever saw a claim on a paper you disagreed with or got triggered by, and then wanted to reproduce the experiment? Good luck finding the code and the data used in the experiments.
 When CUDA kept having a dominance over OpenCL, AMD introduced HIP – a programming language that closely resembles CUDA. Now it doesn’t take months to port code to AMD hardware, but more and more CUDA-software converts to HIP without problems. The real large and complex code-bases only take a few weeks max, where we found that solved problems also made the CUDA-code run faster.


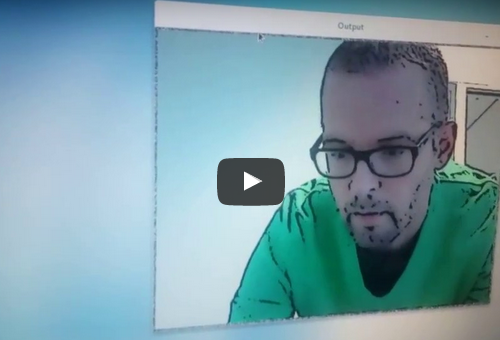
 It takes quite some effort to program FPGAs using VHDL or Verilog. Since several years Intel/Altera has OpenCL-drivers, with the goal to reduce this effort. OpenCL-on-FPGAs reduced the required effort to a quarter of the time, while also making it easier to alter the specifications during the project. Exactly the latter was very beneficiary when creating the demo, as the to-be-solved problem was vaguely defined. The goal was to make a video look like a cartoon using image filters. We soon found out that “cartoonized” is a vague description, and it took several iterations to get the right balance between blur, color-reduction and edge-detection.

 A month ago IWOCL (OpenCL workshop) and DHPCC++ (C++ for GPUs) took place. Meanwhile many slides and posters have been
 Most of our projects are around performance optimisation, but we’re cleaning up bugs too. This is because you can only speed up software when certain types of bugs are cleared out. A few months ago, we got a different type of request. If we could solve bugs in MESA 3D that appear in games.
 In the perfect world all software is fast, giving us time to do actual work. Unfortunately we live in an unperfect world, and we have to spend extra time controlling our anger as the software keeps us waiting.




 As of 1 April we are 7 years old. Because of all the jokes on that day, this post is a bit later.
 There have been more times when we wanted to support the community more. The first try was OpenCL:PRO and did not live long, as it was actually unclear to us what “the community” wanted.
 With

